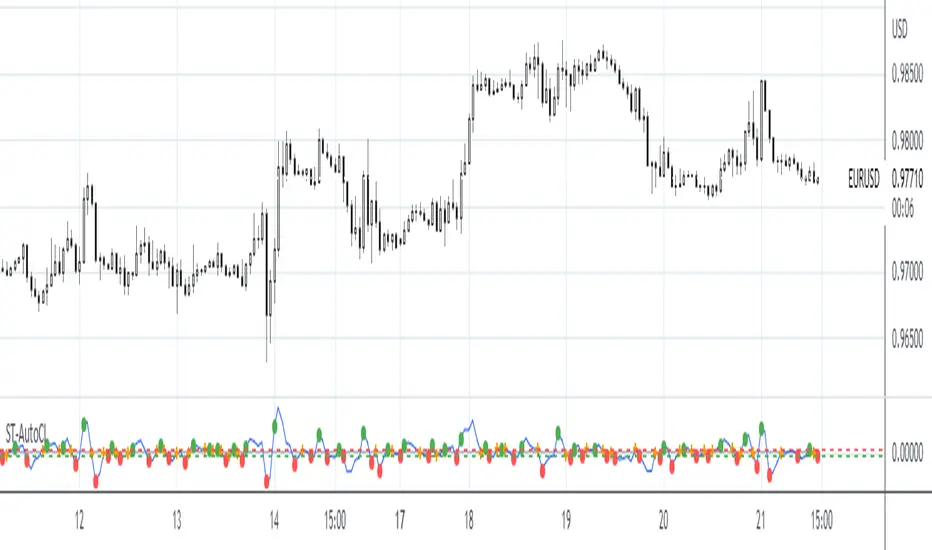
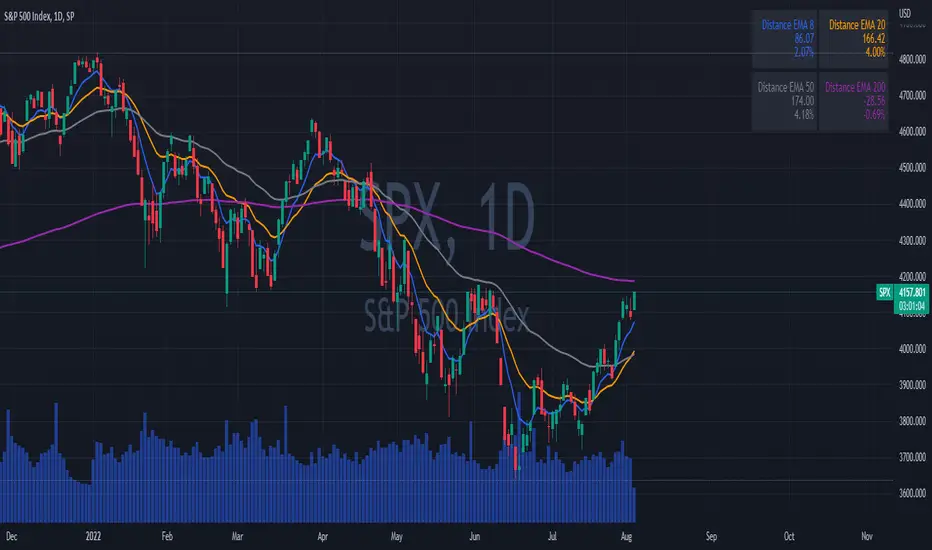
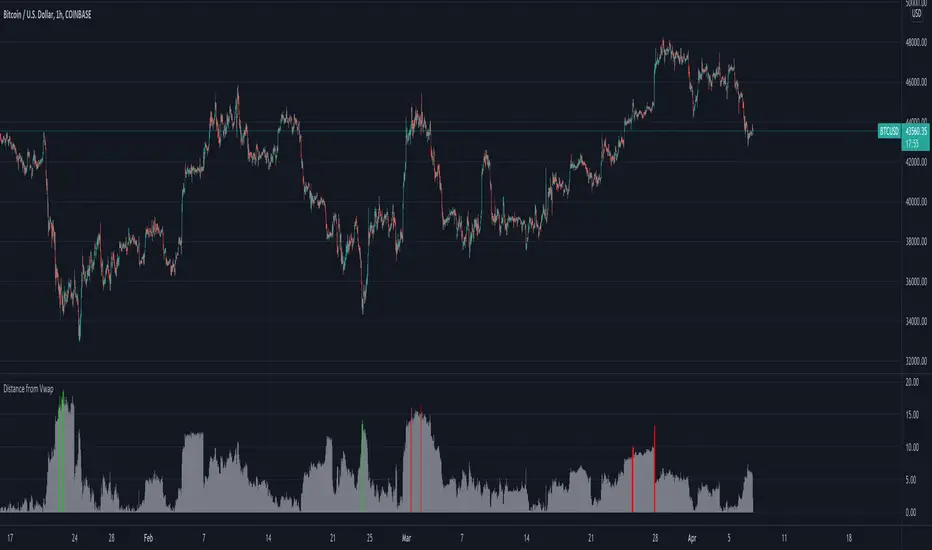
Indicator

Supply Demand AI [PickMyTrade]Supply Demand AI asks the question every supply/demand tool skips: when price returns to a zone, does this arrival look like the ones that reversed — or like the ones that ate straight through?
Every supply/demand indicator draws the zone. None of them score the arrival. This one does. Each time price re-enters a zone, nine properties of the return are frozen before the outcome is known — approach speed, prior tap count, zone age, departure strength, base tightness, base volume, trend pressure, relative volume and zone width — and the arrival is voted on by a Lorentzian nearest-neighbour search over every similar return this chart has already resolved. The result is stated in the past tense: of the arrivals that looked like this, X% produced the configured reaction move before the zone failed.
The script also scores two doctrines stated everywhere in supply/demand teaching and measured almost nowhere: whether fresh zones genuinely outperform tapped ones on this chart, and whether heavy-volume bases genuinely outperform quiet ones. The info table reports what actually happened, not what the doctrine says should have.
――――――――――――――――――――――――――――――――――――――
🔷 WHAT IT MEASURES
🔸 Zone formation — base-and-departure, not pivot clustering A zone is born from a run of compressed candles (the base) followed by an impulsive leg away of a configurable ATR multiple within a fixed window — the Rally-Base-Drop / Drop-Base-Rally shape, detected as a sequence rather than asserted from a single bar. A pivot cluster has no departure to measure; a base-and-departure zone has three properties frozen at birth that a pivot never carries: how hard the market left, how tight the base was, and which side was trading volume while it sat there.
🔸 Zone geometry The origin block (solid segment) marks the actual base candles. The projection (lighter band) carries those prices forward to where they can be tested. The departure measure (vertical bar on the departure candle) shows the full distance the move reached — readable straight off the price scale. Freshness is written as text ("fresh" / "2 taps"), not encoded in a line style that has to be decoded.
🔸 Outcome — reaction magnitude, not hold-or-break A return that drives the configured ATR multiple back away from the zone edge before closing decisively through it = REACTED. A return that closes beyond the far edge by the break buffer = FAILED. A return that does neither inside the timeout window = STALLED and discarded from training — price sitting inside a zone is not evidence either way.
🔸 Two doctrine read-outs The info table reports the freshness edge (did untouched zones react more often than tapped ones on this chart?) and the base-volume edge (did heavy-volume bases outperform quiet ones?). Either can come back negative, and the table says so when it does.
――――――――――――――――――――――――――――――――――――――
🔷 THE LORENTZIAN NEAREST-NEIGHBOUR CLASSIFIER
🔸 Why Lorentzian, not Naive Bayes A Naive Bayes model was the obvious alternative and is the wrong tool here: it assumes the features are conditionally independent given the class. Departure strength, base tightness and zone width all describe the same underlying impulse from three angles — multiplying their densities counts one piece of evidence three times. A nearest-neighbour vote makes no independence assumption at all. It asks a narrower, more honest question: of the returns already resolved on this chart, what happened to the ones that arrived most like this one?
🔸 Distance metric Distance is Lorentzian — log(1 + |a − b|) — applied per axis and summed. Against a library of this size, plain Euclidean distance lets one outlier axis dominate; the log compresses extremes, so a return that is typical on eight features and unusual on the ninth still finds its true neighbours.
🔸 Shared library — supply and demand in one pool Every feature is written relative to the direction of the test, so a fast approach into demand and a fast approach into supply are the same event described the same way. Sharing one library across both directions doubles the effective sample count without mixing unlike distributions.
🔸 Shrinkage The neighbour vote is shrunk toward the library's own base rate. Without it, k unanimous neighbours read as a certainty the sample size cannot support. The shrinkage weight is expressed in neighbour-equivalents so it is independent of k.
🔸 Honest caveat — stated here, not buried in a tooltip The classifier learns as history replays, so loading a different amount of chart history changes how many returns have trained it and therefore the percentage shown on a zone. The zones themselves, their boundaries and which bars they appear on are unaffected. This is inherent to on-chart learning.
――――――――――――――――――――――――――――――――――――――
🔷 SIGNALS AND DISPLAY
🔸 Zone appearance Full-strength blue (demand) or orange (supply) border at or above the conviction threshold. Muted at the opposite end. Neutral while price is inside — the zone is neither reacting nor failing yet. Grey once consumed. A zone born from twice the required departure draws with a heavier border — the one property worth reading before any text.
🔸 Zone label Nearest live demand, nearest live supply, and any zone with a return open right now receive a worded label: zone type · departure in ATR · evidence grade (A–D) · tap count · classifier read. Every other zone speaks through colour alone, which caps visible labels at roughly three regardless of timeframe or zoom.
🔸 Evidence grade (A–D) Measures accumulated evidence only — departure strength (35%), base tightness (25%), resolved return count (20%), age (20%). Deliberately excludes the classifier's probability so the grade and the percentage remain two different statements: the grade says how much stands behind the zone; the percentage says how similar arrivals resolved.
🔸 Return history ticks A coloured tick inside the zone at every bar where one of its own returns resolved — blue for a reaction, orange for a failure. Renders each zone's individual track record in place so the percentage can be read against the evidence behind it.
🔸 Order flow band A band above the trend EMA while cumulative volume delta is rising, below it while delta is falling. Opacity scales with how strong that pressure is against its own recent range — a faint band means the tape is undecided; a solid band means one side is leaning on it. Context, not a signal: it says which side is pressing when price arrives at a zone.
🔸 Info table Zones on chart · returns graded · overall reaction rate · freshness edge · base-volume edge · base-flow edge · live order flow direction and z-score · nearest demand and supply with ATR distance. Reads LEARNING until the warmup sample count is met.
🔸 Alerts Four alertcondition() calls: price entered a zone · return reacted · return failed · any resolved return. Worded as observations. Recommended alert setting: Once Per Bar Close.
――――――――――――――――――――――――――――――――――――――
🔷 INPUTS
🔸 Zone Detection Base Candle Max Range (ATR ×) — a candle counts as base while its range is below this multiple. Lower = cleaner zones, fewer of them. Default 0.60. Min / Max Base Candles — fewest and most candles that form a valid base. Default 1 / 6. Departure Strength (ATR ×) — how far price must travel from the base before the base qualifies as a zone. The single most important setting. Default 1.60. Departure Window (bars) — bars allowed for the departure to reach its target. Default 5. Zone Boundaries — Wick or Body extent for the base. Wick is the conservative read. Default Wick. Minimum Zone Height (ATR ×) — floor on zone thickness, expanded symmetrically about the base midpoint. Default 0.45. ATR Period — volatility yardstick for all distances. Default 14.
🔸 Return Resolution Reaction Target (ATR ×) — how far back away from the zone counts as a REACTION. Default 1.50. Break Buffer (ATR ×) — how far beyond the far edge price must CLOSE to count as a failure. Default 0.30. Return Timeout (bars) — bars a return stays open before being discarded as STALLED. Default 20. Zone Consumed On — Wick Touch / Body Touch / 50% Fill / Full Fill. Governs retirement only; returns always measure from the first wick. Default Body Touch. Max Returns Per Zone — a zone revisited this many times behaves like a range boundary. Default 4.
🔸 Probability Engine Warmup Samples — resolved returns required before the classifier replaces the running reaction rate. Default 25. Neighbours Compared — k in the nearest-neighbour vote. Smaller = more local; larger drifts toward the library rate. Default 8. Conviction Threshold — probability at or above which a zone draws at full conviction. Default 0.62. Approach Window — bars used to measure how fast price entered the zone. Default 5. Volume Baseline — averaging window for relative volume. Default 20. Trend EMA Period — reference for the trend-pressure feature. Default 50.
🔸 Order Flow Order Flow Band — show / hide. Default on. Flow Momentum Period — lookback for the rate of change of CVD. Default 14. Flow Band Width (ATR ×) — height of the band from the EMA to its outer edge. Default 1.00. Flow Normalisation Window — z-score window so the band reads the same across instruments. Default 50.
🔸 Visual Demand / Supply / In-zone / Consumed Colours · Show Zones · Zone Labels · Return History Ticks · Keep Consumed Zones · Max Live Zones (cap on live slots; consumed zones are free) · Zones Per Side (nearest N zones above and below price) · Show Zones Within ATR × (safety ceiling) · Label Every Zone · Label Size · Zone Border Width · Zone Evidence Grade.
🔸 Display Zen Mode — hides labels and info table; zones and ticks remain. Show Info Table.
――――――――――――――――――――――――――――――――――――――
🔷 REQUIREMENTS AND LIMITATIONS
🔸 The classifier reads what this chart has seen — not a pre-trained model and not a fixed statistical table. On a chart with thin history or a symbol the market has recently repriced, the library may be small and the read thin. The sample count travels with every zone label and the table header so this is never hidden. 🔸 Loading a different amount of chart history changes how many returns have trained the classifier, which changes the percentage shown on a zone. The zones themselves are unaffected — this is inherent to on-chart instance-based learning. 🔸 Zone geometry is fixed at birth and never re-centred. No request.security() call is made anywhere. Test state advances only on barstate.isconfirmed. No future data is referenced. 🔸 The departure is measured over bars that have already closed. A zone appears on the bar its departure qualifies and never moves afterwards. 🔸 Base volume and base flow are estimated from the close-position formula — a synthetic proxy, not true bid/ask data. The classifier adapts to the noise, but the quality of the read improves on instruments with genuine intrabar price travel. 🔸 The evidence grade (A–D) and the classifier percentage are two different statements by design. Do not read either alone. 🔸 Past resolved returns are hypothetical observations — no commission, no slippage — and are not a record of trading results. This script does not issue trade instructions and nothing in it is financial advice.
――――――――――――――――――――――――――――――――――――――
Built natively in Pine Script® v6. Lorentzian k-nearest-neighbour classifier trained on-chart from resolved supply/demand returns — no external libraries, no lookahead, no repainting. Zone formation uses a base-and-departure state machine; outcome is reaction magnitude, not hold-or-break. Attribution: the Rally-Base-Drop / Drop-Base-Rally construction is long-established public technical analysis, implemented independently here. The evidence grade and drawing layer are shared with the author's own Support Resistance AI — stated here plainly rather than left for a reader to find.
Open source — Mozilla Public License 2.0. Indicator

Trailing Stop Quality [AGPro Series]Trailing Stop Quality
🧠 Core Idea
Is the current trailing reference defending the move cleanly, or is it creating noise that deserves a risk review?
📌 Overview / What it does
Trailing Stop Quality is a trade-management planner built for traders who want more context around active trailing stops, defense rails, and risk-shift conditions.
The script compares a swing defense rail with a volatility defense rail, evaluates trend-defense quality, measures pullback depth, checks volatility expansion, and converts the result into a 0-100 trailing stop quality score.
It produces trail rails, a centered risk-shift zone, a target-room guide, compact state labels, alerts, and a clean AGPro panel. It does not predict price direction, automate trading, or tell users what to buy or sell.
🎯 Purpose & Design Philosophy
Many trailing stop tools show a stop line, but they do not explain whether the current trail is structurally clean, too close to noise, too loose, or in conflict with another management reference.
This script was built to fill that gap.
It helps traders who already have a move in progress and want to evaluate whether the active trail is still defending the move with enough quality to keep monitoring.
The design philosophy is simple: manage context before reacting to the line.
⚡ Why This Script Is Different
Most tools focus on plotting a trailing stop line, flipping side, or marking stop transitions.
This script does NOT clone a Chandelier Exit flip-zone tool, does not act as a stop-loss optimizer, and does not print direct trade commands.
Instead, it scores the quality of the current trail using swing defense, volatility defense, trend slope, pullback depth, volatility expansion, and rail conflict. The result is a management-readiness layer, not another raw stop signal.
⚙️ Methodology
1. Context Detection
The script reads the active management side automatically or lets the user force long-side or short-side evaluation.
2. Reference Mapping
It maps two trail references: a swing defense rail and a volatility defense rail. The tighter reference becomes the active defense rail.
3. Reaction Evaluation
It scores whether the active trail is balanced, too near, too loose, conflicted, or already broken.
4. Visual Output
It displays the active defense rail, swing rail, volatility rail, risk-shift zone, target guide, compact labels, alerts, and AGPro panel state.
🗺️ How to Read the Chart
Zones = the risk-shift zone shows the gap between the swing defense rail and volatility defense rail. Its centered label summarizes the active conflict or quiet state.
Labels = labels mark TRAIL HOLDS, RISK SHIFT, MONITOR, NOISE, ROOM LIMITED, or DEFENSE LOST contexts.
Colors = green highlights clean defense, pink highlights lost defense, amber highlights risk review, and indigo highlights monitor context.
Panel = the panel summarizes Trail Quality, Stop Distance, Trend Defense, Risk Shift, and Action.
🚦 Signals & States
• TRAIL HOLDS → the active trail is defending cleanly with enough score and no major risk-shift conflict.
• RISK SHIFT → price is close to the active rail or swing and volatility rails disagree enough to deserve review.
• MONITOR → trail quality is acceptable but not strong enough for a clean defense state.
• NOISE → the current trail reference is low quality or too unstable.
• ROOM LIMITED → forward room is limited relative to the active trail risk.
• DEFENSE LOST → price crossed the active defense rail and the current trail context should be reviewed.
🔔 Alerts Logic
Alerts trigger when the script detects a clean trail-hold state, risk-shift state, monitor state, noisy trail state, defense-loss event, or limited target-room condition.
Alerts are attention markers only.
They are not trade instructions and should be interpreted within broader market context.
🧩 Confluence Logic
The strongest context appears when swing defense and volatility defense are aligned, the active trail distance is balanced, trend slope supports the management side, pullback depth is controlled, and volatility is expanding without becoming chaotic.
When those conditions align, the 0-100 trail quality score improves.
📊 When to Use
• During active trend-following management
• After a move has already started and trailing references matter
• When comparing swing-based trail behavior with volatility-based defense
• During pullbacks where the trail may be too close to price
• When evaluating whether a move still has reasonable room before the next structure edge
⚠️ When NOT to Use
• Very low-liquidity symbols with erratic wick behavior
• Extremely noisy chop where no stable management side exists
• Event-driven spikes where volatility changes too quickly
• Charts where the user wants entry signals instead of trail-quality context
🎛️ Key Inputs
• Management Side → controls Auto, Long Management, or Short Management mode.
• Swing Trail Lookback → controls the structural defense rail.
• Volatility Rail Multiple → controls the ATR-based volatility defense rail.
• Sensitivity → adjusts how strict the trail-quality scoring model is.
• Minimum Clean Score → defines when the trail can qualify as a clean defense state.
• Target Guide R Multiple → sets the forward planning reference used for target-room context.
• Visual settings → control rails, risk-shift zone, target guide, labels, panel location, panel theme, and font sizes.
🖥️ Interface & Visual Design
The interface is intentionally chart-first.
The rails show the actual management references, the zone shows swing-versus-volatility conflict, and the panel gives a fast decision read without turning the script into a crowded dashboard.
The AGPro panel uses a single merged blue header row and keeps the key state visible at a glance.
🧪 Practical Usage Workflow
1. Read the panel Trail Quality state.
2. Check whether the active defense rail is still below price in long management or above price in short management.
3. Review the risk-shift zone to see whether swing and volatility references agree.
4. Check whether the target guide still has reasonable forward room.
5. Use the label state as an attention marker, then confirm with broader structure and market context.
🔍 Interpretation Guidelines
Think of the output as trail-quality context, not a trade signal.
A high score means the active trail is better aligned with structure, volatility, trend defense, and pullback depth.
A low score means the current trailing reference may be too noisy, too close, too loose, or already losing defensive value.
🚫 What This Script Is NOT
• Not a prediction engine
• Not financial advice
• Not auto trading
• Not guaranteed signals
• Not a Chandelier Exit clone
• Not a stop-loss optimizer
• Not a buy or sell signal tool
⚠️ Limitations & Transparency
Trailing stop quality can change quickly when volatility expands, contracts, or when price moves into noisy pullback conditions.
Different timeframes may produce different trail rails and score behavior.
Fast markets, low liquidity, and abnormal wick behavior can reduce the usefulness of any rule-based trail-quality model.
🧠 Market Context Notes
Trail quality is not only about distance from price.
It also depends on whether structure is still defending the move, whether volatility is stable enough to support the rail, and whether the next target area leaves enough room relative to current trail risk.
🧾 Use Case Examples
When price trends higher and both swing defense and volatility defense remain below price with a strong score, the script may mark TRAIL HOLDS.
When price compresses toward the active trail or swing and volatility rails separate too much, the script may mark RISK SHIFT.
When price crosses the active defense rail, the script may mark DEFENSE LOST so the user can review the management context.
🧱 System Philosophy
Trailing Stop Quality belongs to the AGPro planner-style family: tools designed to help traders evaluate context before decisions, rather than simply adding another signal to the chart.
🔐 Non-Promise Statement
No output from this script guarantees a result.
No score represents certainty.
📉 Risk Disclosure
Trading involves risk.
Users are responsible for their own decisions, position sizing, and risk management.
This script is for educational and analytical purposes only and does not provide financial advice.
📚 Educational Note
The goal is to make trailing stop context easier to inspect by separating clean defense, risk shift, noisy trails, limited room, and lost defense states.
Indicator

Chandelier Exit Flip Zones [AGPro Series]Chandelier Exit Flip Zones
Chandelier Exit Flip Zones is a premium ATR trailing-stop and exit-state engine built for traders who want more than a simple stop line on the chart.
The script takes the classic Chandelier Exit concept and turns it into a structured decision layer:
Chandelier trail -> trail-side flip -> flip quality -> continuation state -> exit-pressure awareness
The result is a clean public-free tool for reading trend continuation, trailing-stop pressure, and Chandelier flip transitions without turning the chart into a crowded signal board.
📌 Why This Script Exists
Chandelier Exit is one of the most practical and searched trailing-stop concepts because it connects trend direction with volatility. Many traders use it to trail positions, judge when momentum is still holding, or identify when price is starting to lose distance from its active stop area.
Most Chandelier tools stop at the line.
This script adds the missing context:
- Which side of the Chandelier trail is active?
- How far is price from the trail in ATR terms?
- Was the latest trail flip strong or weak?
- Is the market still in continuation mode?
- Is price compressing back into an exit-watch area?
- Did the transition create a clean forward flip zone?
That extra layer is what makes the script more useful than a standard ATR trailing-stop overlay.
⚡ What Makes It Different From Standard Chandelier Exit Indicators
Most public Chandelier Exit indicators are visually simple. They usually plot a long stop, a short stop, and sometimes a basic flip marker.
Chandelier Exit Flip Zones is built around a stronger reading model.
It evaluates each trail flip through a quality score that combines:
- Trail-break strength
- EMA trend agreement
- Range expansion
- Candle close location
- Optional volume participation
This means the script does not treat every flip equally. A weak flip inside chop is not presented with the same weight as a cleaner transition with better structure, stronger expansion, and better directional agreement.
The script also uses quality-filtered Flip Zones. These boxes are not generic support and resistance areas. They are drawn around the Chandelier transition area where price breaks the previous trail and establishes a new active side. The purpose is to mark the actual trail-flip area, not to fill the chart with unrelated levels.
🧭 How It Is Different From Other AGProLabs Scripts
This script was intentionally kept in a narrow Chandelier Exit lane so it does not overlap with other AGProLabs public releases.
It is not a SuperTrend script. SuperTrend logic is built around a different volatility-band mechanism, while this tool is built around Chandelier high/low structure anchors and ATR trail distance.
It is not an ATR compression or ATR breakout script. Those concepts focus on volatility contraction, breakout pressure, or expansion behavior. This script focuses on the active trailing-stop side, distance from the Chandelier trail, and exit-state awareness.
It is not a generic trend dashboard. The panel is compact and centered on trail side, ATR multiple, distance, flip quality, and continuation or exit-watch state.
It is not a support/resistance zone engine. The only zones are concept-native Flip Zones created from qualified Chandelier trail transitions.
This keeps the script differentiated, practical, and publication-safe inside the AGPro Series catalog.
✅ Core Features
- Chandelier Exit trail based on ATR distance and recent structure anchors
- Long-side and short-side trail state
- Bullish and bearish trail-flip detection
- Flip quality score from 0 to 100
- Prime, qualified, and developing flip classifications
- ATR distance from the active trail
- Percentage distance from the active trail
- Continuation, control, and exit-watch state logic
- Quality-filtered forward Flip Zones
- Optional exit-watch labels, disabled by default for a cleaner public view
- Label cooldown and maximum label controls
- Maximum visible zone control
- Adjustable label font size
- Adjustable panel font size
- Adjustable panel location
- Dark, light, and auto panel theme options
- AGPro-style panel with a single merged blue header row
- Alerts for bullish flips, bearish flips, prime flips, and exit-watch conditions
📊 Panel Readout
The panel is designed to give a fast read without visual overload:
Trail Side
Shows whether the active Chandelier trail is currently long-side or short-side.
ATR Multiple
Shows the volatility multiple used by the current trail.
Distance
Shows how far price is from the active trail in both ATR and percentage terms.
Flip Quality
Displays the most recent flip score and classification.
State
Classifies the current condition as continuation, control, or exit watch.
🎯 How To Read It
A strong Chandelier flip means price has crossed the prior active trail with enough quality to deserve attention. The score helps separate cleaner transitions from weaker flips in noisy conditions.
A continuation state means price has moved far enough from the active trail and still has trend agreement behind it. This is the cleaner trend-following condition.
A control state means price is on one side of the trail, but the continuation profile is not yet strong enough to classify as a high-conviction continuation read.
An exit-watch state means price has compressed back toward the active Chandelier trail. This does not make the script a prediction tool. It simply highlights that the active trend has less distance from its trailing-stop structure and deserves closer attention.
💎 Why Traders May Like It
The script is useful because it keeps the original simplicity of Chandelier Exit while adding the context traders usually have to judge manually.
It can help users read:
- Trend-following continuation quality
- ATR trailing-stop distance
- Trail-side transitions
- Cleaner Chandelier flip zones
- Exit-pressure areas near the active trail
- Strong versus weak flip behavior
The default view is intentionally restrained. Exit-watch labels are available, but disabled by default so the first chart impression stays cleaner. Flip labels and zones are also filtered by score so the chart does not get flooded during sideways periods.
🛠 Suggested Use Cases
- Trend-following exit management
- Swing-trading trail awareness
- Crypto trend continuation tracking
- Forex and index trailing-stop context
- Stock trend-state monitoring
- Identifying stronger Chandelier trail transitions
- Monitoring when price compresses back toward the active trail
⚙️ Recommended Default Style
The defaults are tuned for a public-free premium view:
- ATR Length: 22
- Structure Lookback: 22
- ATR Multiple: 3.0
- Flip Zones: enabled
- Minimum Zone Score: 50
- Minimum Flip Label Score: 45
- Exit Labels: disabled by default
- Label Font Size: Normal
- Panel Font Size: Normal
- Panel Theme: Dark
These settings keep the tool immediately usable while preserving a clean chart presentation.
🔹 In One Sentence
Chandelier Exit Flip Zones turns a classic ATR trailing stop into a cleaner Chandelier trail, flip-quality, continuation-state, and exit-pressure map built for serious chart reading without unnecessary clutter. Indicator

Library

Indicator

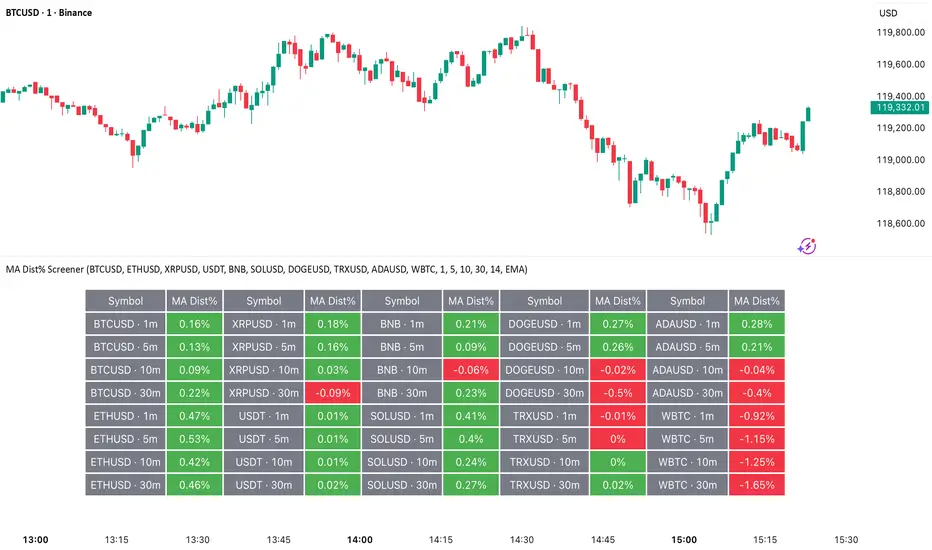
MA Dist% Screener [Pineify]MA Distance Screener: Multi-Asset Market Scanner for TradingView
Screen multiple symbols and multiple timeframes on TradingView with the MA Distance Screener. Compare asset prices to flexible moving average types. Visual table view, custom assets, timeframes, and MA types. Supercharge your TradingView screener, optimize your workflow, and catch opportunities across assets in real time.
Key Features
Screen up to 10 custom symbols simultaneously across four configurable timeframes.
Choose from multiple Moving Average types: EMA, SMA, WMA, HMA, RMA, VWMA for flexible market context.
Visualize real-time % distance between price and moving average per asset/timeframe in a clean, color-coded table.
Highly customizable: Set your own symbol list, timeframes, MA length and type.
Alerts for symbol/MA deviations—instantly see overbought/oversold status with intuitive background coloring.
Optimized for crypto, FX, and traditional assets – all asset types supported.
How It Works
The MA Distance Screener acts as a dynamic multi-symbol, multi-timeframe scanner. For each selected symbol and timeframe, it calculates the percentage distance between the latest close price and the selected type of moving average (EMA/SMA/etc.). This is achieved by making secure `request.security` calls per asset/timeframe combination, retrieving updated values for each matrix cell. The computed distance (%) is displayed in a color-coded table: a positive value signals price above the MA (potential trend strength), while negatives indicate price below the MA (potential weakness or retracement). Custom colors highlight extreme overbought/oversold readings for quick visual cues.
Trading Ideas and Insights
Quickly spot assets showing the largest deviation from their moving averages – ideal for mean reversion or trend-following entries.
Identify clusters of assets and timeframes lining up in overbought or oversold states; optimize entries with multi-timeframe confirmation.
Scan the market in one glance—reduce chart-hopping and never miss an opportunity when multiple assets align for signals.
The ability to scan distance-to-MA across assets and periods gives traders a statistical edge, surfacing hidden pivots, breakouts, and mean-reversion trades that single-chart analysis may miss.
How Multiple Indicators Work Together
At its core, this screener allows the trader to configure what gets scanned—pick your top 10 assets and favorite 4 timeframes. With each matrix cell, the selected MA (e.g., 14-period EMA) is recalculated, and the current price's distance (%) from that value is computed. By offering six distinct moving average algorithms (EMA, SMA, RMA, HMA, WMA, VWMA), traders can choose their preferred method, adapting the screener for trend, swing, or mean-reversion style. All values are visualized in a single table, creating a true "market dashboard" effect for real-time cross-asset assessment.
Unique Aspects
True cross-asset, cross-timeframe screening in a unified table—rare for Pine Script indicators.
Full flexibility—customizable list of assets, timeframes, and MA parameters to suit any market/trading plan.
Intuitive color-coding and table display eliminates guesswork, enabling “at-a-glance” screening and rapid decision-making.
Efficient, optimized Pine v6 codebase—minimal lag even with 40+ concurrent streams.
How to Use
Add the indicator to your TradingView chart (overlay: off, use a clean chart).
In the settings panel, enter up to 10 symbols (tickers) you want to screen—crypto, stocks, FX, or indices.
Set the 4 timeframes to scan (e.g., 1m, 5m, 15m, 1h), plus your preferred moving average length and type.
Review the results in the pop-up table, where each cell shows "% Distance" from MA for each symbol/timeframe.
Monitor table background/text color for overbought vs. oversold cues.
Customization
Symbol List: Track any asset by typing its TradingView ticker.
Timeframes: Full freedom to select 4 timeframes per scan, from 1min to monthly.
MA Config: Choose period length and MA algorithm (classic or exotic types).
Color Themes: Easily spot signals with dynamic color backgrounds and customizable thresholds.
Conclusion
The MA Distance Screener is a must-have tool for systematic traders, portfolio managers, and retail chartists seeking a true multi-asset edge. With real-time cross-checking against multiple moving averages and timeframes, it empowers faster, more confident decision-making, while reducing chart fatigue and missed setups.
Unlock new insights, catch broad and hidden opportunities, and optimize your market workflow—all in a single TradingView panel.
Indicator

Indicator

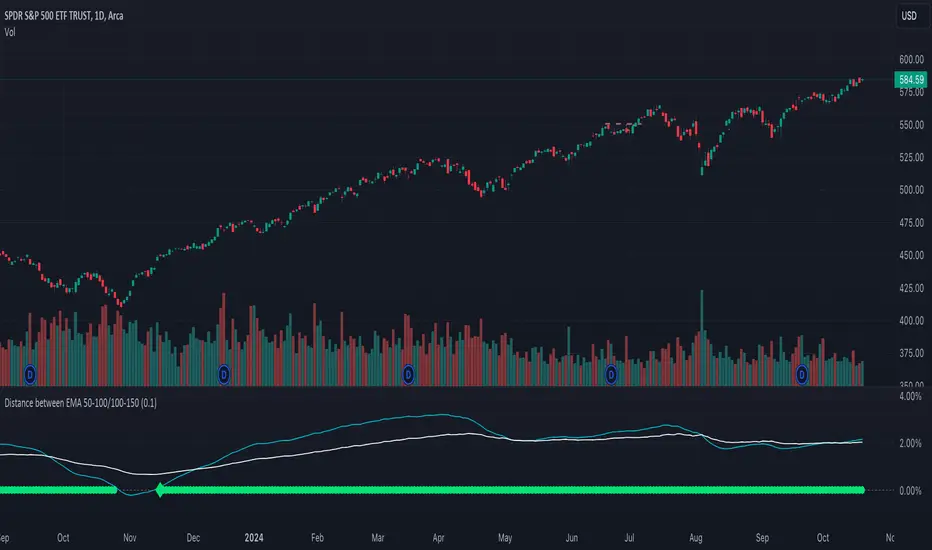
Distance between EMA 50-100/100-150This script calculates and plots the percentage difference between the 50-period, 100-period, and 150-period Exponential Moving Averages (EMA) on a TradingView chart. The aim is to provide a clear visual representation of the market's momentum by analyzing the distance between key EMAs over time.
Key features of this script:
1. EMA Calculation : The script computes the EMA values for 50, 100, and 150 periods and calculates the percentage difference between EMA 50 and 100, and between EMA 100 and 150.
2. Custom Threshold : Users can adjust a threshold percentage to highlight significant divergences between the EMAs. A default threshold is set to 0.1%.
3. Visual Alerts : When the percentage difference exceeds the threshold, a visual marker appears on the chart:
Green Circles for bullish momentum (positive divergence),
Red Circles for bearish momentum (negative divergence),
Diamonds to indicate the first occurrence of new bullish or bearish signals, allowing users to catch fresh market trends.
4. Dynamic Plotting : The script plots two lines representing the percentage difference for each EMA pair, offering a quick and intuitive way to monitor trends.
Ideal for traders looking to gauge market direction using the relationship between multiple EMAs, this script simplifies analysis by focusing on key moving average interactions. Indicator

Indicator

Indicator

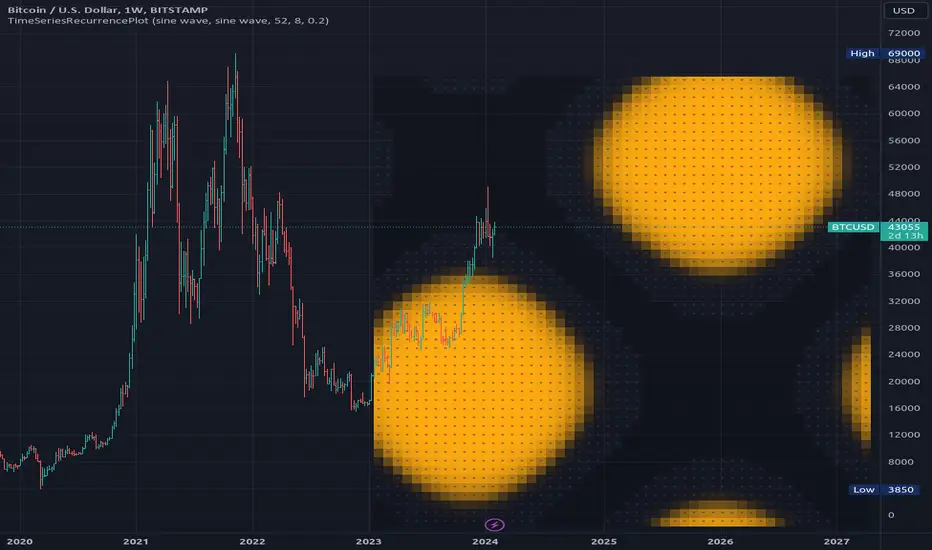
TimeSeriesRecurrencePlotLibrary "TimeSeriesRecurrencePlot"
In descriptive statistics and chaos theory, a recurrence plot (RP) is a plot showing, for each moment i i in time, the times at which the state of a dynamical system returns to the previous state at `i`, i.e., when the phase space trajectory visits roughly the same area in the phase space as at time `j`.
```
A recurrence plot (RP) is a graphical representation used in the analysis of time series data and dynamical systems. It visualizes recurring states or events over time by transforming the original time series into a binary matrix, where each element represents whether two consecutive points are above or below a specified threshold. The resulting Recurrence Plot Matrix reveals patterns, structures, and correlations within the data while providing insights into underlying mechanisms of complex systems.
```
~starling7b
___
Reference:
en.wikipedia.org
github.com
github.com
github.com
github.com
juliadynamics.github.io
distance_matrix(series1, series2, max_freq, norm)
Generate distance matrix between two series.
Parameters:
series1 (float) : Source series 1.
series2 (float) : Source series 2.
max_freq (int) : Maximum frequency to inpect or the size of the generated matrix.
norm (string) : Norm of the distance metric, default=`euclidean`, options=`euclidean`, `manhattan`, `max`.
Returns: Matrix with distance values.
method normalize_distance(M)
Normalizes a matrix within its Min-Max range.
Namespace types: matrix
Parameters:
M (matrix) : Source matrix.
Returns: Normalized matrix.
method threshold(M, threshold)
Updates the matrix with the condition `M(i,j) > threshold ? 1 : 0`.
Namespace types: matrix
Parameters:
M (matrix) : Source matrix.
threshold (float)
Returns: Cross matrix.
rolling_window(a, b, sample_size)
An experimental alternative method to plot a recurrence_plot.
Parameters:
a (array) : Array with data.
b (array) : Array with data.
sample_size (int)
Returns: Recurrence_plot matrix. Library

SimilarityMeasuresLibrary "SimilarityMeasures"
Similarity measures are statistical methods used to quantify the distance between different data sets
or strings. There are various types of similarity measures, including those that compare:
- data points (SSD, Euclidean, Manhattan, Minkowski, Chebyshev, Correlation, Cosine, Camberra, MAE, MSE, Lorentzian, Intersection, Penrose Shape, Meehl),
- strings (Edit(Levenshtein), Lee, Hamming, Jaro),
- probability distributions (Mahalanobis, Fidelity, Bhattacharyya, Hellinger),
- sets (Kumar Hassebrook, Jaccard, Sorensen, Chi Square).
---
These measures are used in various fields such as data analysis, machine learning, and pattern recognition. They
help to compare and analyze similarities and differences between different data sets or strings, which
can be useful for making predictions, classifications, and decisions.
---
References:
en.wikipedia.org
cran.r-project.org
numerics.mathdotnet.com
github.com
github.com
github.com
Encyclopedia of Distances, doi.org
ssd(p, q)
Sum of squared difference for N dimensions.
Parameters:
p (float ) : `array` Vector with first numeric distribution.
q (float ) : `array` Vector with second numeric distribution.
Returns: Measure of distance that calculates the squared euclidean distance.
euclidean(p, q)
Euclidean distance for N dimensions.
Parameters:
p (float ) : `array` Vector with first numeric distribution.
q (float ) : `array` Vector with second numeric distribution.
Returns: Measure of distance that calculates the straight-line (or Euclidean).
manhattan(p, q)
Manhattan distance for N dimensions.
Parameters:
p (float ) : `array` Vector with first numeric distribution.
q (float ) : `array` Vector with second numeric distribution.
Returns: Measure of absolute differences between both points.
minkowski(p, q, p_value)
Minkowsky Distance for N dimensions.
Parameters:
p (float ) : `array` Vector with first numeric distribution.
q (float ) : `array` Vector with second numeric distribution.
p_value (float) : `float` P value, default=1.0(1: manhatan, 2: euclidean), does not support chebychev.
Returns: Measure of similarity in the normed vector space.
chebyshev(p, q)
Chebyshev distance for N dimensions.
Parameters:
p (float ) : `array` Vector with first numeric distribution.
q (float ) : `array` Vector with second numeric distribution.
Returns: Measure of maximum absolute difference.
correlation(p, q)
Correlation distance for N dimensions.
Parameters:
p (float ) : `array` Vector with first numeric distribution.
q (float ) : `array` Vector with second numeric distribution.
Returns: Measure of maximum absolute difference.
cosine(p, q)
Cosine distance between provided vectors.
Parameters:
p (float ) : `array` 1D Vector.
q (float ) : `array` 1D Vector.
Returns: The Cosine distance between vectors `p` and `q`.
---
angiogenesis.dkfz.de
camberra(p, q)
Camberra distance for N dimensions.
Parameters:
p (float ) : `array` Vector with first numeric distribution.
q (float ) : `array` Vector with second numeric distribution.
Returns: Weighted measure of absolute differences between both points.
mae(p, q)
Mean absolute error is a normalized version of the sum of absolute difference (manhattan).
Parameters:
p (float ) : `array` Vector with first numeric distribution.
q (float ) : `array` Vector with second numeric distribution.
Returns: Mean absolute error of vectors `p` and `q`.
mse(p, q)
Mean squared error is a normalized version of the sum of squared difference.
Parameters:
p (float ) : `array` Vector with first numeric distribution.
q (float ) : `array` Vector with second numeric distribution.
Returns: Mean squared error of vectors `p` and `q`.
lorentzian(p, q)
Lorentzian distance between provided vectors.
Parameters:
p (float ) : `array` Vector with first numeric distribution.
q (float ) : `array` Vector with second numeric distribution.
Returns: Lorentzian distance of vectors `p` and `q`.
---
angiogenesis.dkfz.de
intersection(p, q)
Intersection distance between provided vectors.
Parameters:
p (float ) : `array` Vector with first numeric distribution.
q (float ) : `array` Vector with second numeric distribution.
Returns: Intersection distance of vectors `p` and `q`.
---
angiogenesis.dkfz.de
penrose(p, q)
Penrose Shape distance between provided vectors.
Parameters:
p (float ) : `array` Vector with first numeric distribution.
q (float ) : `array` Vector with second numeric distribution.
Returns: Penrose shape distance of vectors `p` and `q`.
---
angiogenesis.dkfz.de
meehl(p, q)
Meehl distance between provided vectors.
Parameters:
p (float ) : `array` Vector with first numeric distribution.
q (float ) : `array` Vector with second numeric distribution.
Returns: Meehl distance of vectors `p` and `q`.
---
angiogenesis.dkfz.de
edit(x, y)
Edit (aka Levenshtein) distance for indexed strings.
Parameters:
x (int ) : `array` Indexed array.
y (int ) : `array` Indexed array.
Returns: Number of deletions, insertions, or substitutions required to transform source string into target string.
---
generated description:
The Edit distance is a measure of similarity used to compare two strings. It is defined as the minimum number of
operations (insertions, deletions, or substitutions) required to transform one string into another. The operations
are performed on the characters of the strings, and the cost of each operation depends on the specific algorithm
used.
The Edit distance is widely used in various applications such as spell checking, text similarity, and machine
translation. It can also be used for other purposes like finding the closest match between two strings or
identifying the common prefixes or suffixes between them.
---
github.com
www.red-gate.com
planetcalc.com
lee(x, y, dsize)
Distance between two indexed strings of equal length.
Parameters:
x (int ) : `array` Indexed array.
y (int ) : `array` Indexed array.
dsize (int) : `int` Dictionary size.
Returns: Distance between two strings by accounting for dictionary size.
---
www.johndcook.com
hamming(x, y)
Distance between two indexed strings of equal length.
Parameters:
x (int ) : `array` Indexed array.
y (int ) : `array` Indexed array.
Returns: Length of different components on both sequences.
---
en.wikipedia.org
jaro(x, y)
Distance between two indexed strings.
Parameters:
x (int ) : `array` Indexed array.
y (int ) : `array` Indexed array.
Returns: Measure of two strings' similarity: the higher the value, the more similar the strings are.
The score is normalized such that `0` equates to no similarities and `1` is an exact match.
---
rosettacode.org
mahalanobis(p, q, VI)
Mahalanobis distance between two vectors with population inverse covariance matrix.
Parameters:
p (float ) : `array` 1D Vector.
q (float ) : `array` 1D Vector.
VI (matrix) : `matrix` Inverse of the covariance matrix.
Returns: The mahalanobis distance between vectors `p` and `q`.
---
people.revoledu.com
stat.ethz.ch
docs.scipy.org
fidelity(p, q)
Fidelity distance between provided vectors.
Parameters:
p (float ) : `array` 1D Vector.
q (float ) : `array` 1D Vector.
Returns: The Bhattacharyya Coefficient between vectors `p` and `q`.
---
en.wikipedia.org
bhattacharyya(p, q)
Bhattacharyya distance between provided vectors.
Parameters:
p (float ) : `array` 1D Vector.
q (float ) : `array` 1D Vector.
Returns: The Bhattacharyya distance between vectors `p` and `q`.
---
en.wikipedia.org
hellinger(p, q)
Hellinger distance between provided vectors.
Parameters:
p (float ) : `array` 1D Vector.
q (float ) : `array` 1D Vector.
Returns: The hellinger distance between vectors `p` and `q`.
---
en.wikipedia.org
jamesmccaffrey.wordpress.com
kumar_hassebrook(p, q)
Kumar Hassebrook distance between provided vectors.
Parameters:
p (float ) : `array` 1D Vector.
q (float ) : `array` 1D Vector.
Returns: The Kumar Hassebrook distance between vectors `p` and `q`.
---
github.com
jaccard(p, q)
Jaccard distance between provided vectors.
Parameters:
p (float ) : `array` 1D Vector.
q (float ) : `array` 1D Vector.
Returns: The Jaccard distance between vectors `p` and `q`.
---
github.com
sorensen(p, q)
Sorensen distance between provided vectors.
Parameters:
p (float ) : `array` 1D Vector.
q (float ) : `array` 1D Vector.
Returns: The Sorensen distance between vectors `p` and `q`.
---
people.revoledu.com
chi_square(p, q, eps)
Chi Square distance between provided vectors.
Parameters:
p (float ) : `array` 1D Vector.
q (float ) : `array` 1D Vector.
eps (float)
Returns: The Chi Square distance between vectors `p` and `q`.
---
uw.pressbooks.pub
stats.stackexchange.com
www.itl.nist.gov
kulczynsky(p, q, eps)
Kulczynsky distance between provided vectors.
Parameters:
p (float ) : `array` 1D Vector.
q (float ) : `array` 1D Vector.
eps (float)
Returns: The Kulczynsky distance between vectors `p` and `q`.
---
github.com Library

Indicator

Library

Library

Indicator

Indicator

Indicator

Indicator

Indicator

Indicator

Indicator